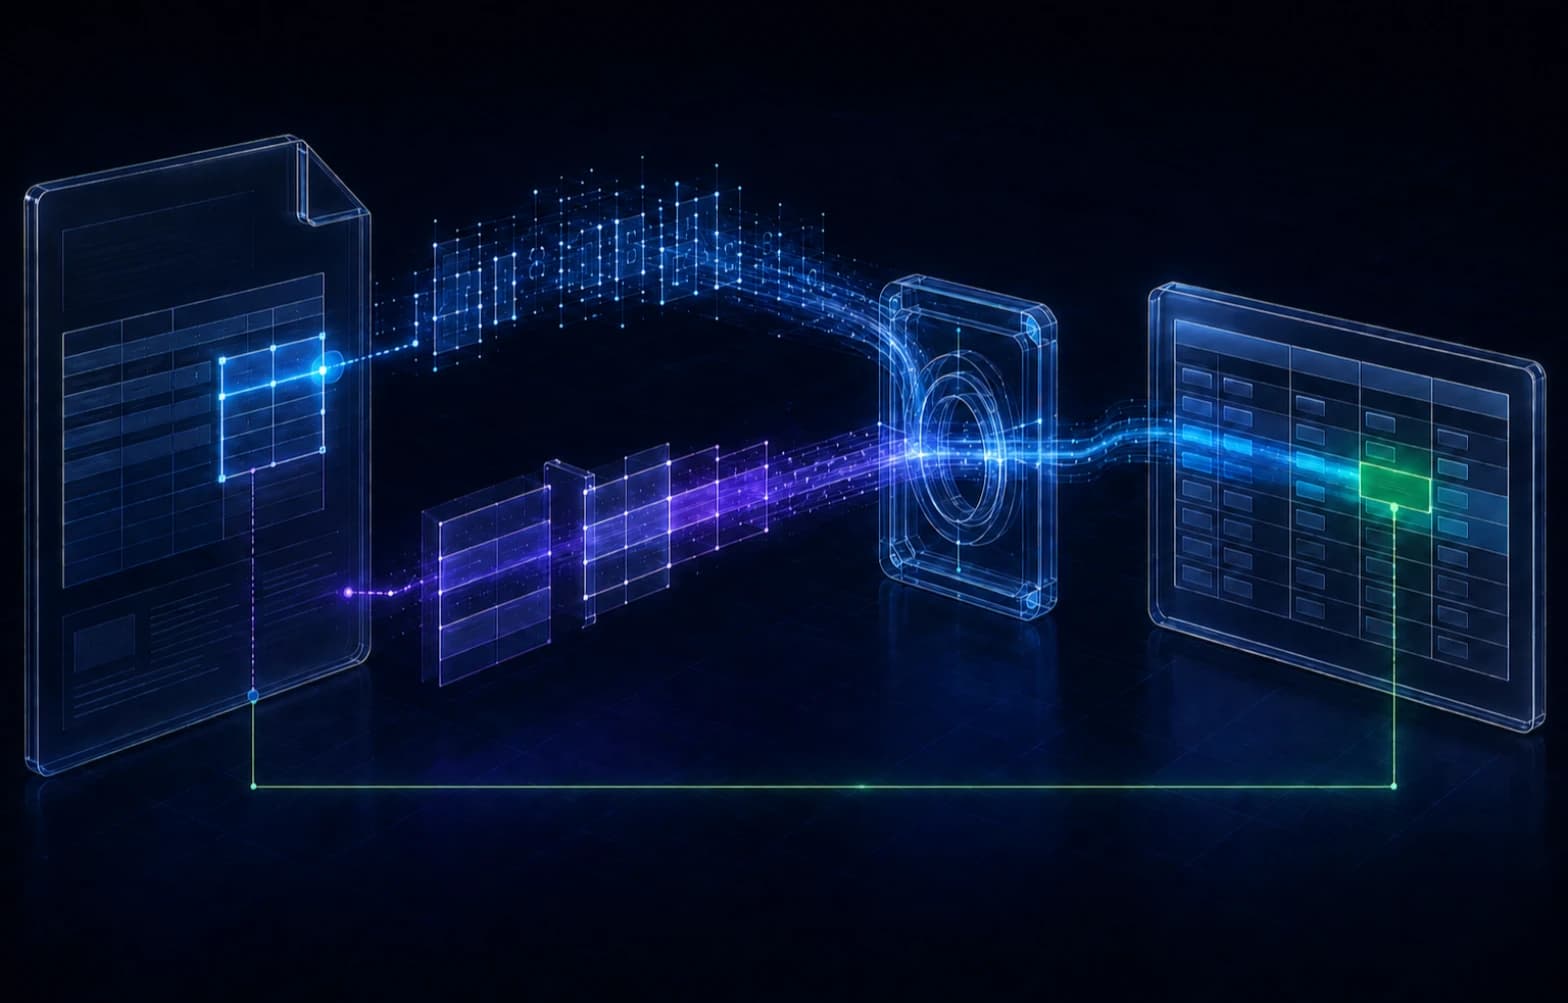

Document Intelligence extracts tables from PDF files and associates each cell with its source content. The application combines Azure Document Intelligence (Azure DI) for table structure with PyMuPDF for embedded text and page geometry.
This article describes the extraction architecture, coordinate normalization, cell-matching rules, and source review workflow. It also explains the limits of validation against a PDF text layer.
Problem
Azure DI can identify rows, columns, cells, and merged headers while returning an incorrect value for an individual cell. Correct table structure does not guarantee correct text extraction.
For example, a PDF might contain 99,999 while the extracted cell contains 99.999. The cell can occupy the correct row and column even though its numeric separator has changed. If a downstream application interprets the period as a decimal separator, it can assign a different numeric value.
Other discrepancies include:
- Missing characters: a currency symbol or nil-marker dash appears in the PDF text but is absent from Azure’s reading.
- Spacing differences: the extractors disagree about whitespace within a value.
- Selection markers: Azure returns
:selected:or:unselected:for a detected checkbox, including false detections in blank table cells. - Missing verification data: a scanned page has no usable embedded text against which to check OCR output.
The pipeline addresses these cases by retaining both readings and applying explicit source-selection rules. It preserves numeric punctuation instead of applying a document-wide replacement rule.
The separator mismatch is an illustrative example. The matcher tests cover source selection, whitespace normalization, missing symbols, and selection markers. The fixture results described below are a separate evaluation.
Architecture
The extraction pipeline assigns each component a specific responsibility:
- PyMuPDF: extract embedded text, word coordinates, metadata, and page geometry; render PDF pages.
- Azure DI: identify table structure and document layout; provide OCR readings where needed.
- Normalizer: convert both outputs into a shared coordinate system and associate PDF words with table cells.
- Canonical data model: retain cell values, source readings, and matching metadata.
- Review interface: display the extracted table alongside the PDF and expose the evidence for a selected cell.
PyMuPDF runs before Azure DI. The matching stage uses geometric rules and normalized text comparisons. It does not use a language model or fuzzy string matching.
Matching is deterministic for the same extracted inputs and configuration. Repeating an external extraction request can produce different inputs, so this guarantee applies to matching rather than to every service response. For implementation details, see the extraction pipeline.
Coordinate normalization
Both extraction outputs must use the same coordinate system before the pipeline can associate words with cells. The canonical representation uses:
- PDF points as the unit of measurement.
- The top-left corner as the origin.
- The page’s displayed orientation, with rotation applied.
- Axis-aligned bounding boxes.
PyMuPDF word boxes pass through the page’s rotation matrix. Azure polygons are converted to bounding boxes and scaled to the page dimensions reported by PyMuPDF:
scale_x = pdf_page_width / azure_page_width
scale_y = pdf_page_height / azure_page_height
Page-size ratios account for differences between the dimensions reported by the two extractors. They also avoid assuming a fixed conversion factor for Azure’s coordinate units. See the normalizer.
Cell matching
Cell matching has two stages: assign words to a cell, then select the cell’s text source.
Assign words by containment
A word qualifies for a cell when the fraction of its bounding-box area inside the cell meets the membership threshold:
word_containment = area(word_box ∩ cell_box) / area(word_box)The default threshold is 0.55. For non-overlapping cell boxes, a word cannot have more than 50% of its area inside two cells. This property prevents duplicate assignment when the detected grid satisfies the non-overlap assumption.
The synthetic fixture includes dashes that cross a column boundary, with approximately 68% of the word box in one cell and 32% in the adjacent cell. The membership rule assigns each dash to the first cell.
Select the text source
The matcher joins qualifying words in PyMuPDF’s reading order and applies these rules in order:
- Exact: if the readings agree after comparison normalization, select PyMuPDF text.
- Spatial: if the readings differ but the enclosing word box meets the cell-containment threshold, select PyMuPDF text.
- Weak: if a candidate exists but meets neither rule, retain Azure’s text and record the PyMuPDF candidate.
- None: if no PDF words qualify, retain Azure’s reading without text-layer confirmation.
The spatial threshold also defaults to 0.55. Comparison normalization preserves punctuation. As a result, 99,999 and 99.999 do not count as an exact match. Selecting the PDF value in this example requires a supported spatial match.
Why the matcher uses containment
An earlier rule graded candidates using intersection-over-union (IoU). IoU divides the overlapping area by the combined area of the word and cell boxes. A short value inside a wide cell can have a low IoU even when it belongs to that cell.
This behavior caused valid nil-marker dashes to be rejected in favor of Azure’s empty reading. Containment measures how much of the word box lies inside the cell and avoids penalizing a value for surrounding cell padding. The pipeline still records IoU for inspection, but IoU does not select the text source.
See the matching implementation for the thresholds and comparison rules.
Source provenance
Each cell retains the selected text, Azure’s reading, the PyMuPDF candidate, and the selected source. Matching metadata records the method, containment, IoU, word count, and the bounding box used to highlight the associated text.
In this application, confirmed means supported by the PDF text layer. It does not mean independently verified against ground truth. An incorrect embedded text layer can still produce a confirmed result.
Selection markers are removed when choosing displayed text. For example, a marker-only reading can produce an empty displayed value, while :selected: Yes retains Yes. The original Azure reading remains in azure_text for inspection. See the selection-marker tests.
Review extracted values
The viewer displays the table beside the rendered PDF. To inspect a value:
- Select a table cell.
- Locate the highlighted cell region and associated PDF words.
- Compare the Azure and PyMuPDF readings in the inspector.
- Check the selected source and matching metadata.
The review toolbar navigates between flagged cells, including values without text-layer confirmation and values with low OCR confidence.
Selecting a cell also adjusts the PDF zoom and centers the selected region. The zoom calculation retains surrounding content to help identify the row and column. A minimum viewing window limits magnification for small values such as a single dash. Fixed render scales allow nearby selections to reuse page images. See the viewer documentation and zoom implementation.
Failure handling
If PyMuPDF succeeds and Azure DI fails, the pipeline records a partial extraction. The result retains text, page geometry, metadata, and error details. The stored PDF can be processed again after the service becomes available.
A PyMuPDF failure stops extraction because normalization depends on its page representation. See the pipeline implementation for the failure paths.
Evaluation and limitations
The extraction notes report the following results for a controlled fixture with 570 populated cells:
- IoU ≥ 0.35: 337 cells matched to PDF text, or 59.1%.
- Containment ≥ 0.80: 422 cells matched, or 74.0%.
- Containment ≥ 0.55: 570 cells matched, or 100%.
The fixture consists of a generated PDF and a simulated Azure layout response derived from the same geometry. It exercises known conditions such as merged headers and boundary-straddling dashes. These results measure fixture matching coverage; they do not establish extraction accuracy across arbitrary PDFs. See the extraction notes for the evaluation details.
The approach has the following limits:
- Scanned pages: without usable embedded text, cell values depend on Azure’s reading and remain unconfirmed.
- Incorrect text layers: agreement with embedded text does not establish that the text matches the visible document.
- Incorrect cell geometry: misplaced or overlapping cell boxes can affect word assignment.
- Limited evaluation scope: broader accuracy claims require independently annotated documents with varied layouts and scan quality.
Further evaluation should measure cell-value accuracy, incorrect word assignments, extraction latency, and reviewer effort.
For the complete implementation, see the Document Intelligence repository.