Case file / AI
Document Intelligence
Extract PDF tables with source provenance, geometric text matching, and a review interface that connects values to the original document.
- Repository
- Source available
- Case ID
- DOCUMENT
- Role
- Architecture, extraction pipeline, and viewer
- Focus
- AI systems and product infrastructure
- Stack
- Python · FastAPI · SQLAlchemy · PostgreSQL · PyMuPDF · Azure Document Intelligence · React · TypeScript · TanStack Query · BullMQ · Cloudflare R2
System log
The engineering story
01 · Constraint
The challenge
Azure Document Intelligence can identify a table’s rows, columns, and merged headers while misreading individual values. A number such as 99,999 can be returned as 99.999, or a nil-marker dash can be omitted. The system needs to preserve source readings and make discrepancies inspectable before extracted data is used downstream.
02 · System
The approach
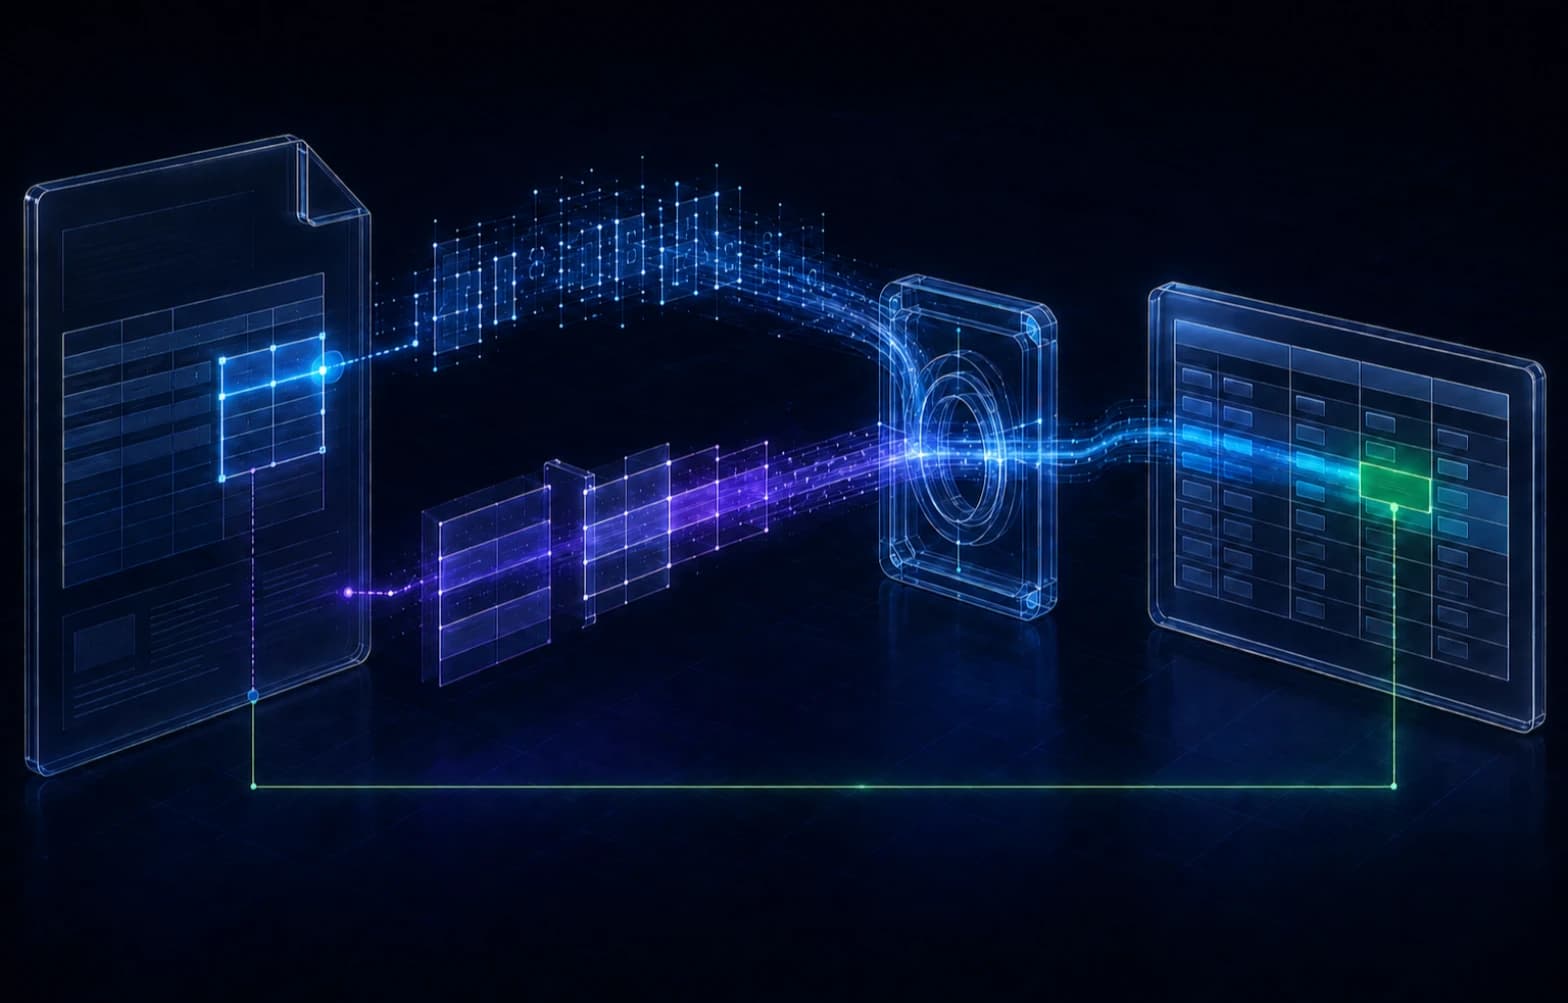
Use Azure DI for table structure and PyMuPDF for embedded text and page geometry. Normalize both outputs into a shared coordinate system, associate words with cells by containment, and record the rule used to select each value. Retain successful PDF extraction as a partial record when Azure fails.
03 · Delivery
What shipped
- 570 of 570 populated cells matched to PDF text in the synthetic fixture; this is not a general extraction-accuracy benchmark
- Cell-level provenance, source-region highlighting, and navigation between unconfirmed or low-confidence readings
- Durable BullMQ-on-Postgres job queue, so extraction runs off the request path without Redis
- Repository-documented suites of 168 Python and 92 frontend tests, including matching and zoom regression coverage
Extraction architecture
The FastAPI upload endpoint stores the PDF and queues extraction, returning an accepted response before processing completes. A background worker produces the canonical document and persists the results in PostgreSQL. The original PDF remains available for rendering and re-extraction.
- Storage: Cloudflare R2 stores original PDFs through a storage abstraction.
- Background jobs: BullMQ uses PostgreSQL for the document queue, avoiding a separate Redis service.
- Persistence: SQLAlchemy models and Alembic migrations organize documents, pages, tables, and cells.
- Frontend: React and TypeScript provide the viewer, with TanStack Query for API data retrieval.
Listing endpoints return metadata rather than full page content or table cells. The viewer requests those larger payloads when a page or table is opened.
Coordinate normalization and source selection
The normalizer converts both outputs into PDF points with a top-left origin and page rotation applied. Azure polygons are scaled using the ratio of the page dimensions reported by the two extractors.
A PDF word belongs to a cell when at least 55% of its bounding-box area falls inside that cell. For non-overlapping cell boxes, this threshold prevents a word from qualifying for two cells. The matcher joins qualifying words in PDF reading order and applies the following rules.
| Method | Condition | Result |
|---|---|---|
| Exact | The normalized readings agree. | Select PyMuPDF text. |
| Spatial | The readings differ, but the candidate meets the containment threshold. | Select PyMuPDF text and retain both readings. |
| Weak | PDF words qualify for the cell, but the candidate meets neither rule above. | Retain Azure text and record the PDF candidate. |
| None | No PDF words qualify for the cell. | Retain Azure text without text-layer confirmation. |
In the illustrative 99,999 versus 99.999 case, punctuation remains significant. The pipeline selects the PDF reading only if the spatial rule supports it. It does not infer the intended number format or replace separators globally.
Containment also avoids an IoU failure mode: a short dash inside a wide cell has little area relative to the cell and can receive a low IoU despite correct placement. IoU remains diagnostic metadata rather than a source-selection criterion.
Review extracted values
Each cell retains the displayed value, both source readings, and the matching method. Containment, word count, and source bounds explain the decision. A reviewer can inspect the evidence without searching the original document manually.
- Select a table cell to highlight its region and associated PDF words.
- Compare Azure’s reading with the PDF text in the cell inspector.
- Inspect the selected source and matching metadata.
- Use the review toolbar to navigate unconfirmed values and low-confidence readings.
The PDF pane zooms to the selected region while keeping adjacent content visible. Fixed rendering scales reuse page images between nearby selections. The table view also supports search and copying tabular data.
Failure recovery
If Azure DI fails after PyMuPDF succeeds, the document is saved with a partial status. Text, coordinates, page geometry, metadata, and error details remain available. Re-extraction runs against the stored PDF after the service recovers.
A PyMuPDF failure stops the pipeline because normalization requires its page representation. Azure retry handling distinguishes transient failures from permanent errors and respects the service’s retry delay.
Evaluation and limitations
The extraction notes report 570 of 570 populated cells matched to PDF text at a containment threshold of 0.55. The fixture includes merged headers, nil-marker dashes across column boundaries, and selection-marker artifacts.
The PDF and simulated Azure response are generated from the same geometry. This provides reproducible regression coverage, but it does not establish accuracy on independently sourced documents.
- Scanned pages without usable embedded text depend on Azure OCR and remain unconfirmed.
- Confirmation against a PDF text layer does not establish that the layer matches the visible page.
- Incorrect or overlapping cell boxes can affect word assignment.
- Broader evaluation requires independently annotated documents and measurements of value accuracy, latency, and reviewer effort.